
Cheng-Chun Hsu
About Me
I am a Ph.D. student in Computer Science at the University of Texas at Austin. I am advised by Prof. Peter Stone. My research focuses on learning robot manipulation from scalable data sources such as human videos. I have also interned at NVIDIA Research, working with Bowen Wen and Stan Birchfield.
Publications [ Google Scholar]
-
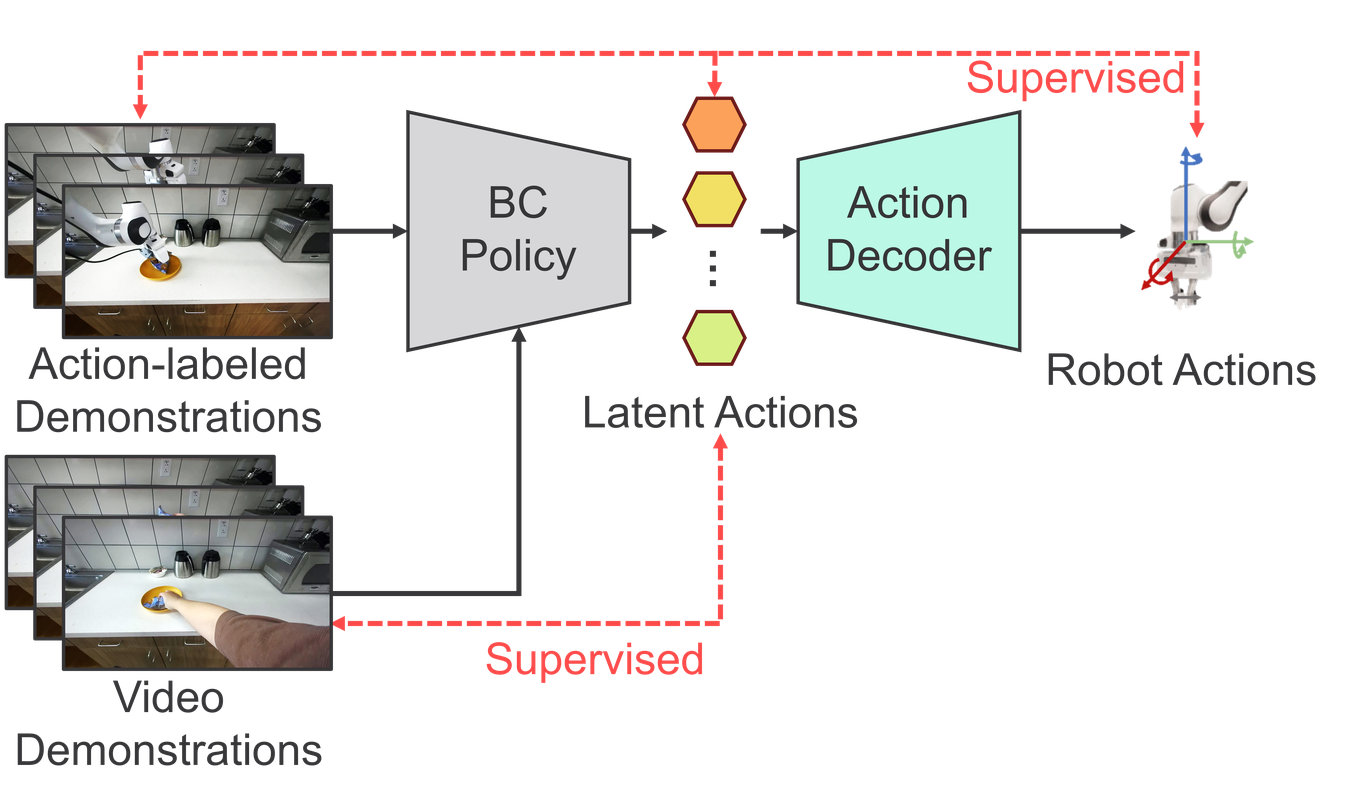 Conference on Robot Learning (CoRL), 2026.
ELA learns robot policies from abundant action-free video plus only a handful of action-labeled demonstrations, by learning latent actions and the policy end-to-end.
-
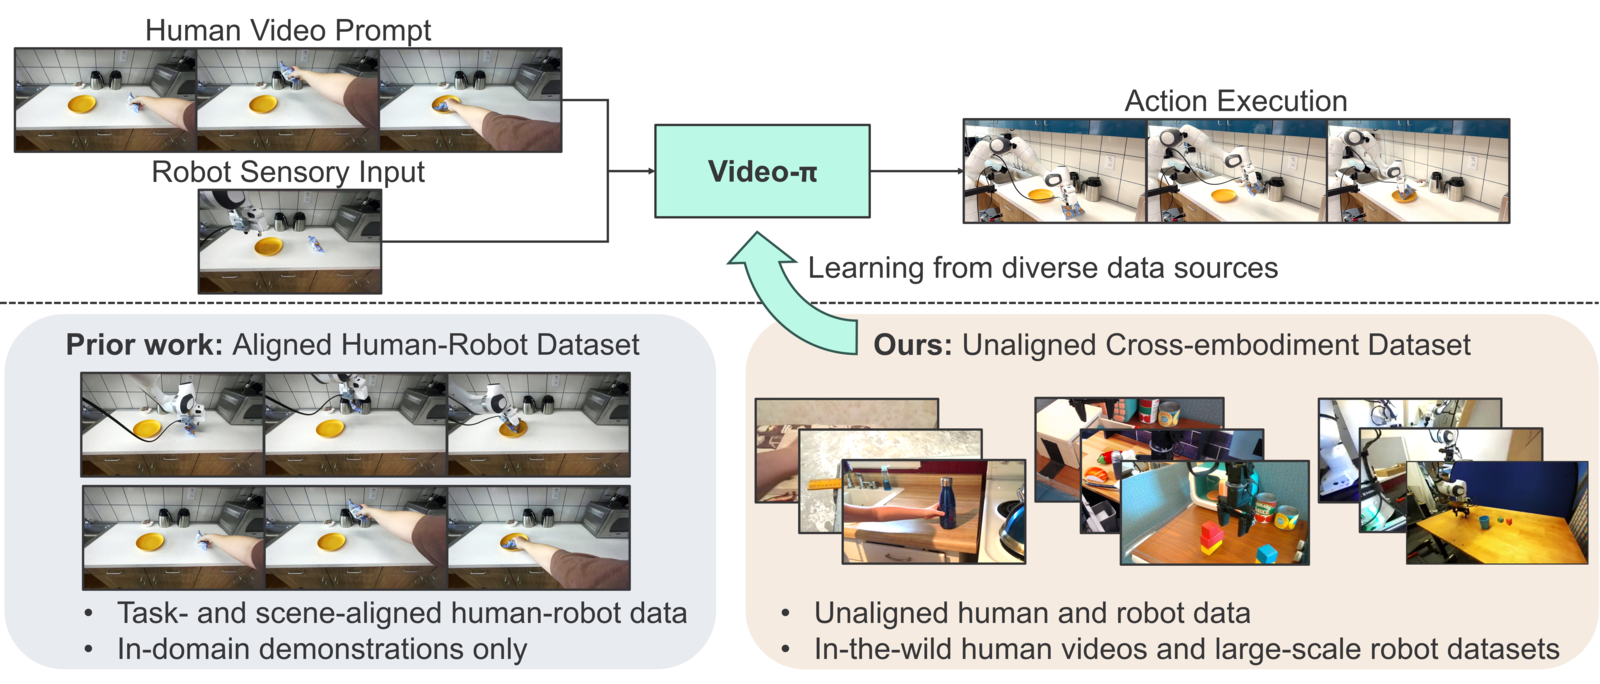 Video-π: Learning a Video-Conditioned Policy from Unaligned Human and Robot DataIn submission.
We learn a video-conditioned policy that lets robots perform tasks shown in human videos, trained from human and robot data that are not paired or aligned.
-
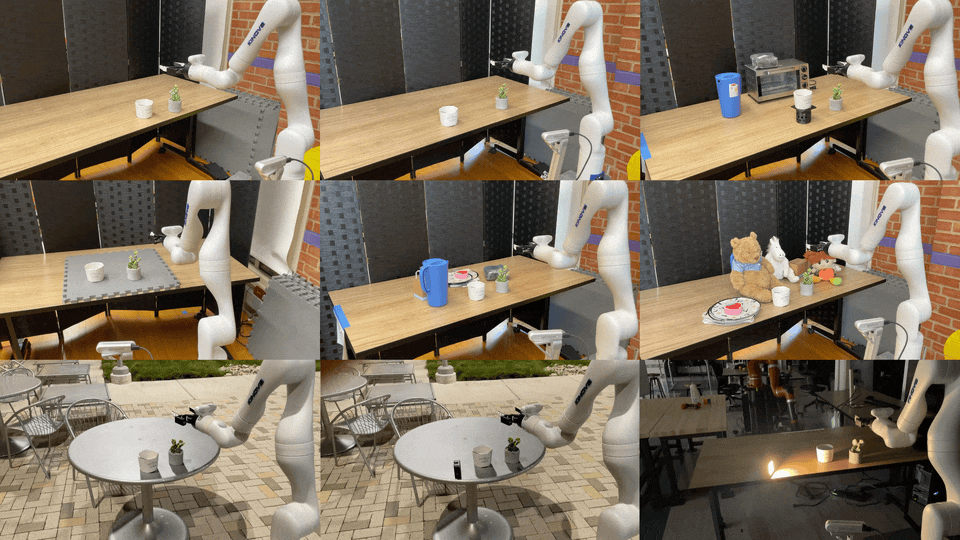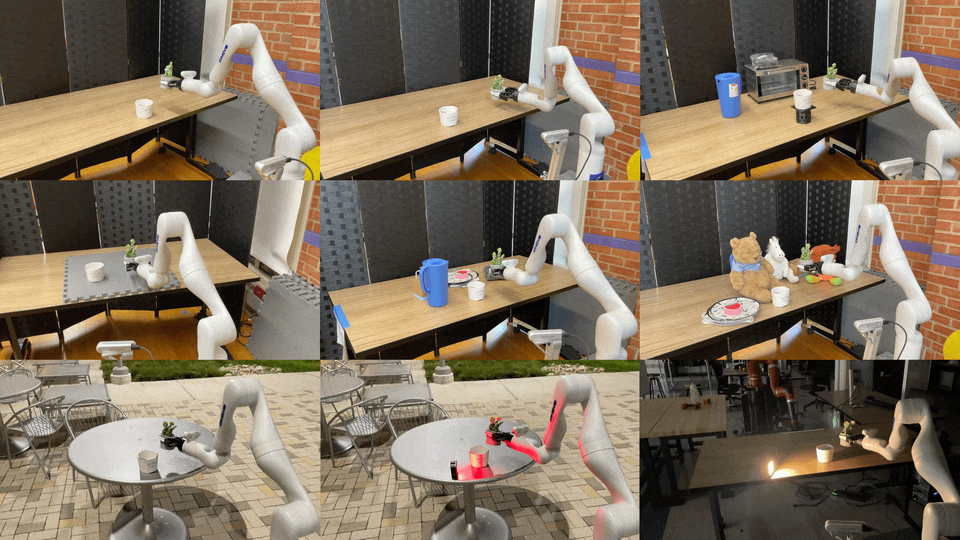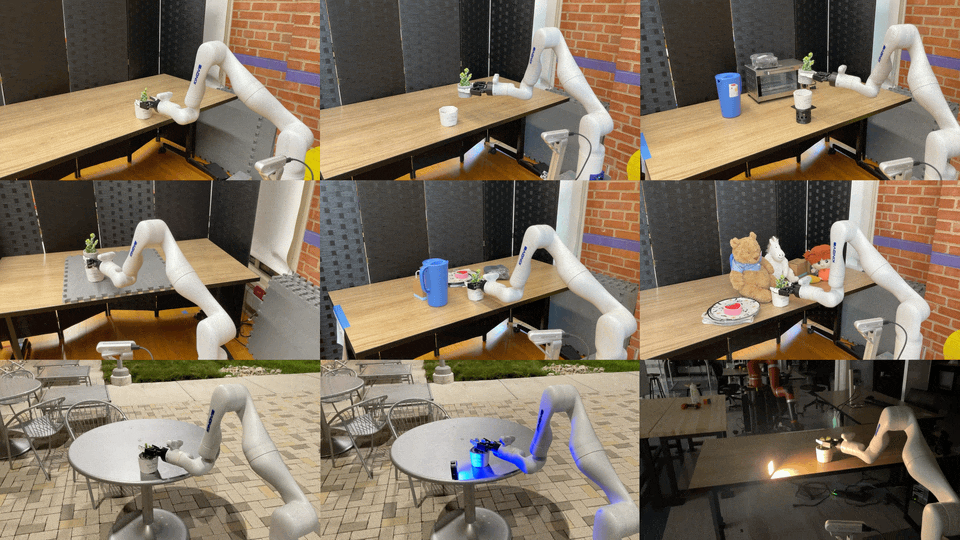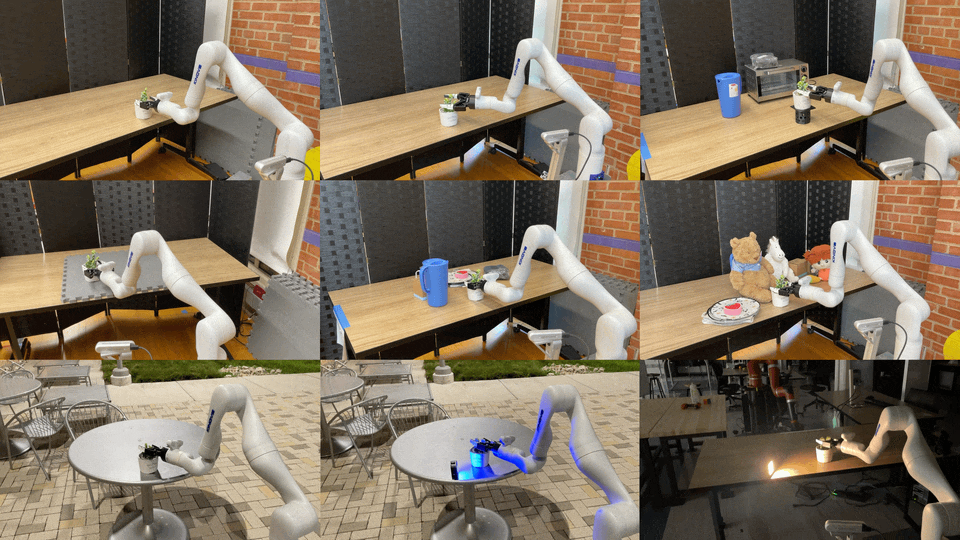 International Conference on Robotics and Automation (ICRA), 2025.
We enable robots to learn everyday tasks from human video demonstrations by usinbg object-centric representation. By predicting future object pose trajectories, SPOT achieves strong generalization capabilities with only eight human video demonstrations.
-
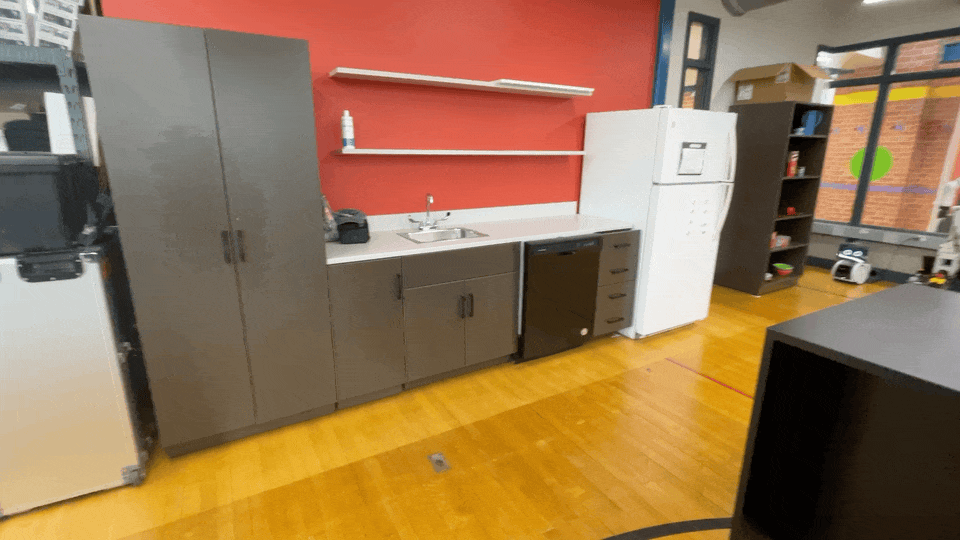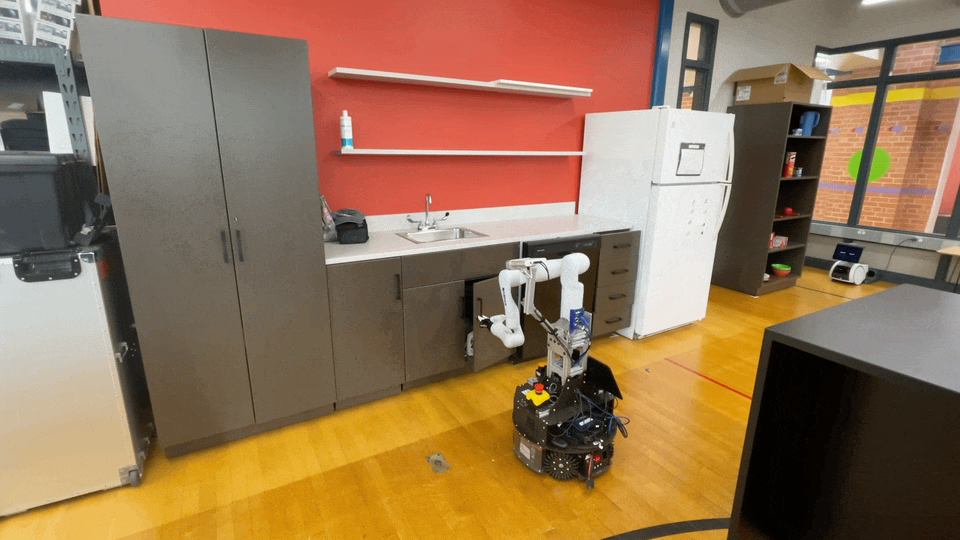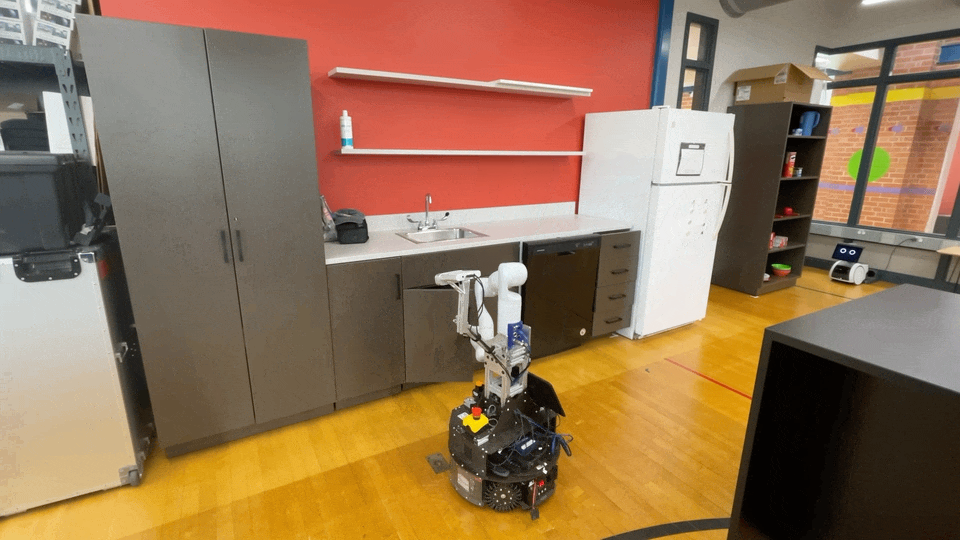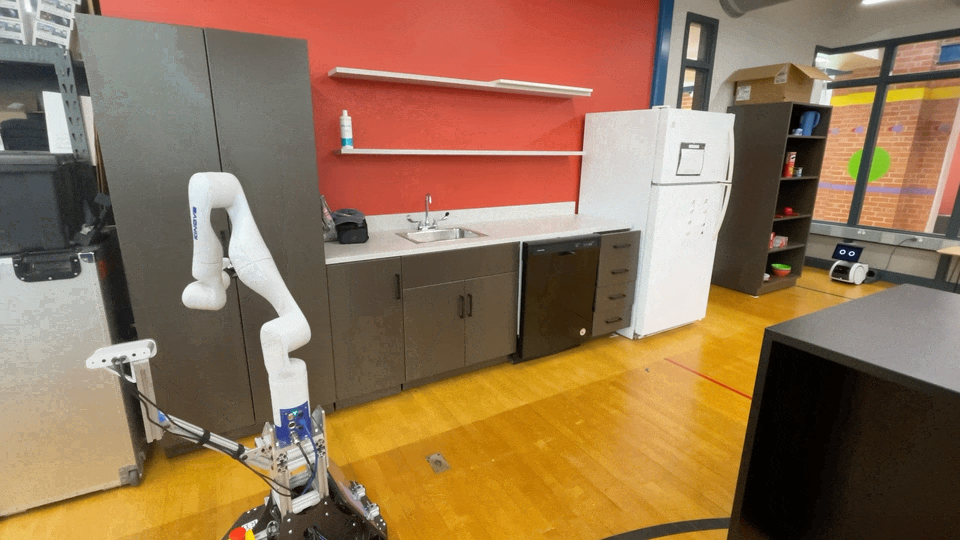 Mobile Manipulation Workshop at ICRA, 2024.Spotlight Presentation
We enable mobile manipulators to perform long-horizon tasks by autonomously exploring and building scene-level articulation models of articulated objects. It maps the scene, infers object properties, and plans sequential interactions for accurate real-world manipulation.
-
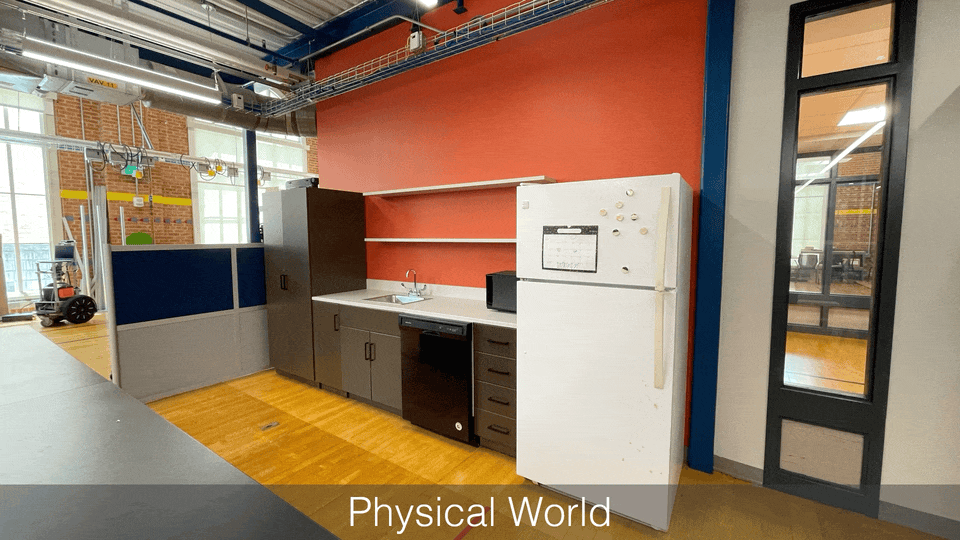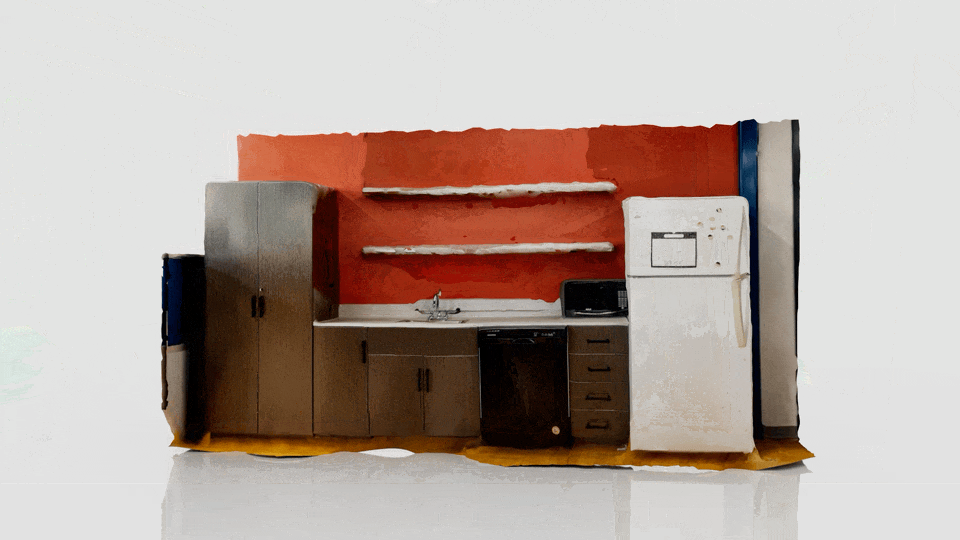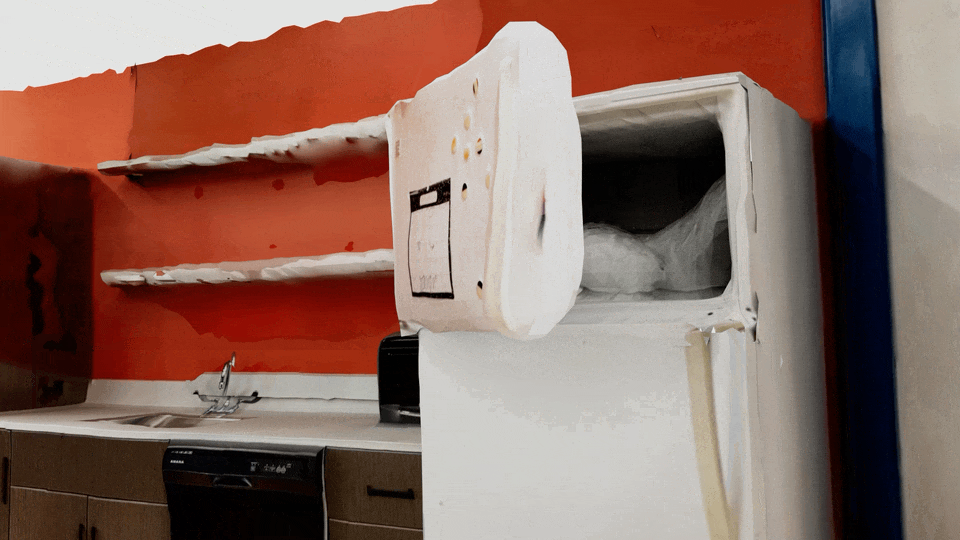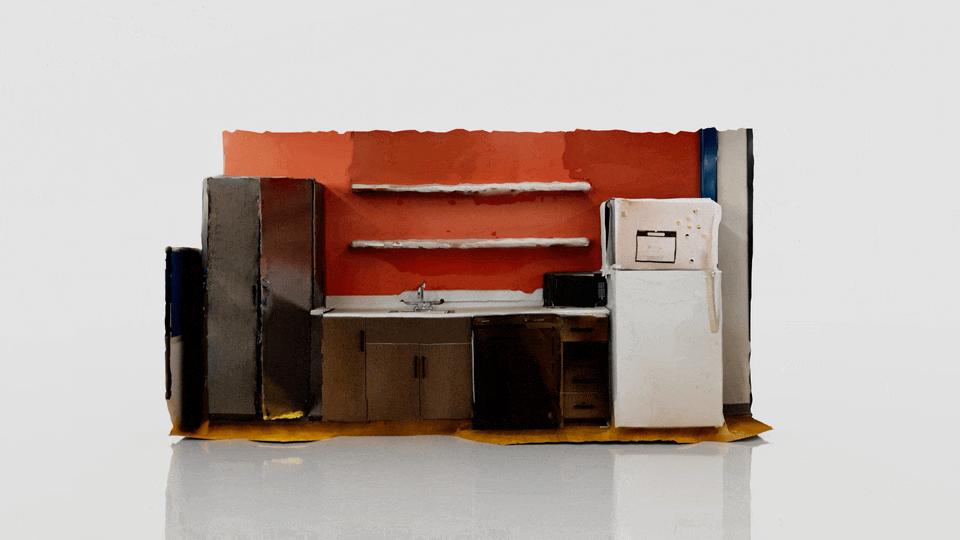 International Conference on Robotics and Automation (ICRA), 2023.
We develop an interactive perception approach for robots to build indoor scene articulation models by efficiently discovering and characterizing articulated objects through coupled affordance prediction and articulation inference.
-
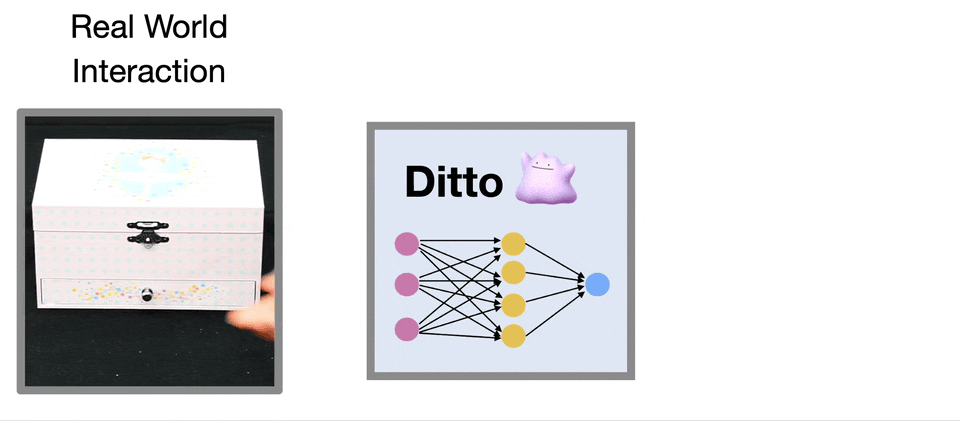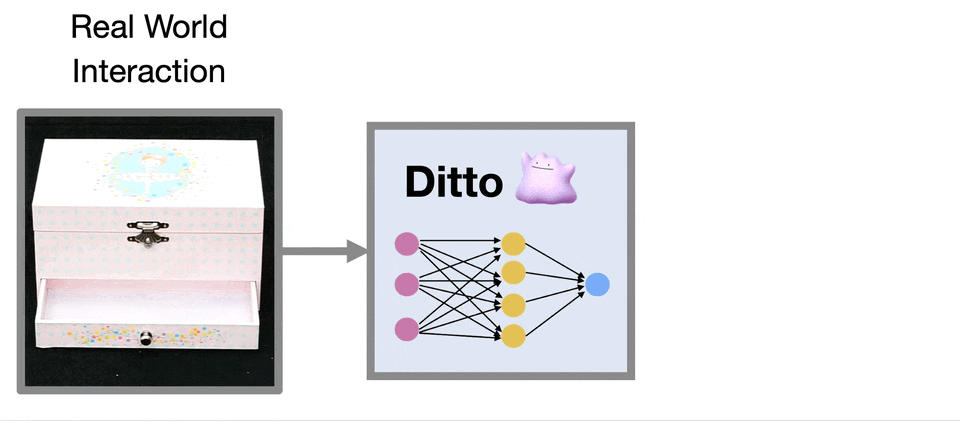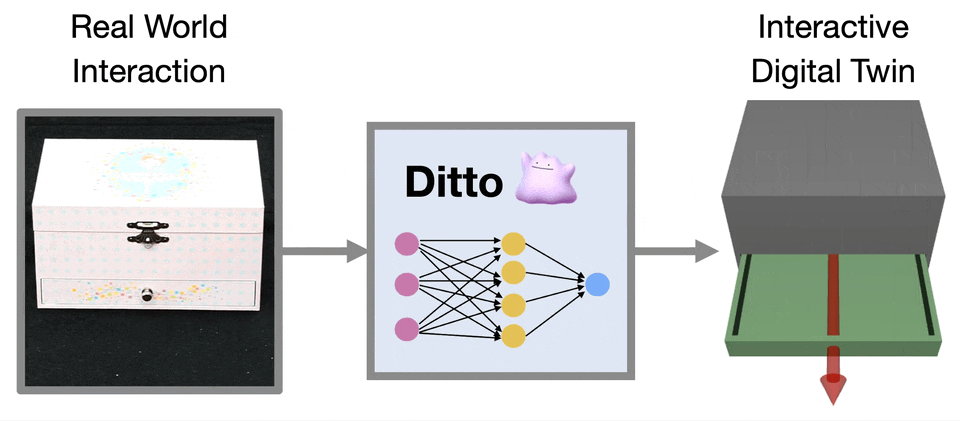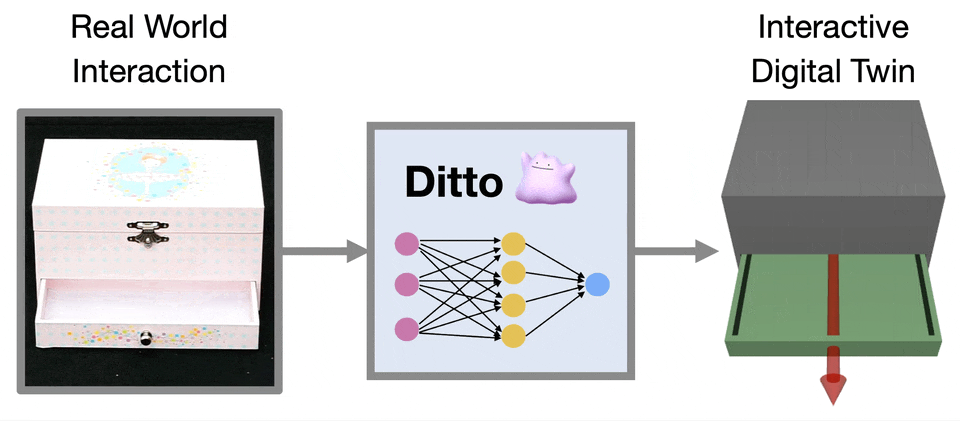 Computer Vision and Pattern Recognition (CVPR), 2022.Oral Presentation
We develop an approach that builds digital twins of articulated objects by learning their articulation models and 3D geometry from visual observations before and after interaction.